9 min read ·
Which Qwen model to run: versions, sizes and VRAM
Qwen3.5 9B needs 6.8 GB, Qwen3.8 27B 17.2 GB, Next 80B 46.5 GB. Compare 11 Qwen models: sizes, context length and the GPU for each.
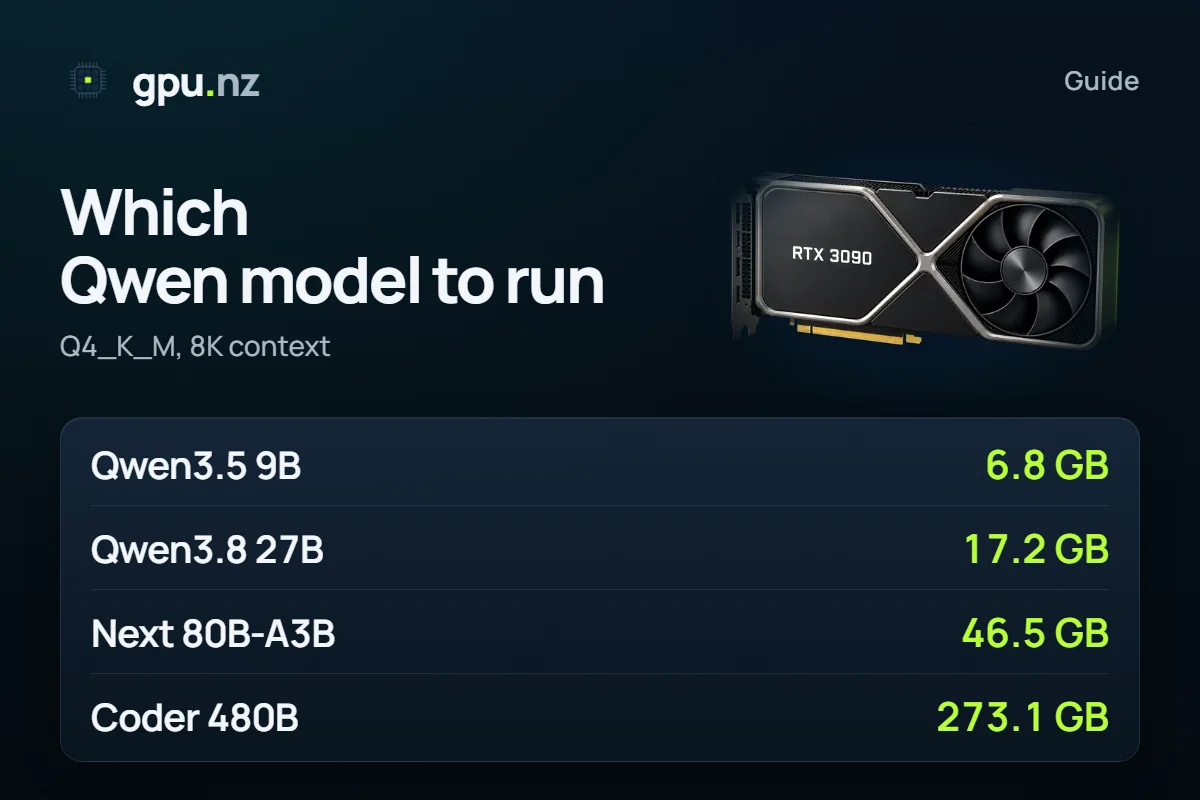
The Qwen model you can run depends on your GPU memory. At Q4_K_M with an 8K context, Qwen3.5 9B needs 6.8 GB, Qwen3.8 27B 17.2 GB, Qwen3 Next 80B-A3B 46.5 GB and Qwen3 Coder 480B-A35B 273.1 GB. These are single-request figures for the 11 family models in the gpu.nz calculator. Below: what separates the generations, which model fits which card and how to run it on a rented GPU.
- Qwen3.5 9B, Q4_K_M, 8K context
- 6.8 GB
- Qwen3.5 9B, Q4_K_M, 8K context
- Qwen3.8 27B, Q4_K_M, 8K context
- 17.2 GB
- Qwen3.8 27B, Q4_K_M, 8K context
- Qwen3 Next 80B-A3B, Q4_K_M, 8K context
- 46.5 GB
- Qwen3 Next 80B-A3B, Q4_K_M, 8K context
- context of Qwen3.8, Qwen3.5, Next and Coder, tokens; Qwen3 has 40K
- 256K
- context of Qwen3.8, Qwen3.5, Next and Coder, tokens; Qwen3 has 40K
Which Qwen models are there?
Qwen is Alibaba's family of open models. The names are easy to mix up: versions, sizes and suffixes all run together. Five lines matter for a GPU in our data.
- Qwen3 — dense models at 8B, 14B and 32B plus two Mixture-of-Experts (MoE) models, 30B-A3B and 235B-A22B. They work with text and think before answering by default.
- Qwen3 Coder — programming models, 30B-A3B and 480B-A35B. The authors built them for agentic coding, and they have no thinking mode.
- Qwen3 Next 80B-A3B — a MoE with 81.3B parameters, 3B of them working on each token. Its attention is hybrid, more on that below.
- Qwen3.5 — the 4B and 9B versions are in the table. They take images along with text.
- Qwen3.8 27B — the newest in the table. Its authors call it the next generation after Qwen3.5 and Qwen3.6, with gains in code, professional work and agents. It takes images and video.
“A3B” and “A22B” mean 3B and 22B active parameters. In a dense model every parameter works on every token.
Part of the family is not in the calculator yet: Qwen3.5 has 27b, 35b and 122b sizes in the Ollama library, Qwen3.8 has Flash-Next and 2.4T-A95B on Hugging Face, and Qwen3.6 is not in the data. We do not count these.
How much VRAM does each Qwen model need?
At Q4_K_M and an 8K context, from 4.1 GB (Qwen3.5 4B) to 273.1 GB (Qwen3 Coder 480B-A35B). Quantisation compresses the weights: the Q4_K_M file of Qwen3.8 27B is 3.3 times smaller than the original BF16, with little loss in answer quality. The total covers the weights, the context cache (memory for the text the model has already read) and the CUDA runtime.
- Qwen3.5 4B4.1 GB
- Qwen3.5 9B6.8 GB
- Qwen3 8B6.8 GB
- Qwen3 14B10.7 GB
- Qwen3.8 27B17.2 GB
- Qwen3 30B-A3BMoE19.1 GB
- Qwen3 Coder 30B-A3BMoE19.1 GB
- Qwen3 32B21.4 GB
- Qwen3 Next 80B-A3BMoE46.5 GB
The whole family in one table: parameters, file size, memory at two context lengths, the smallest card and the context limit set in each model's config.
| Model | Parameters | Q4_K_M weights | Memory at 8K / 32K | Smallest card | Context limit |
|---|---|---|---|---|---|
| Qwen3.5 4B | 4.7B | 2.6 GB | 4.1 / 4.8 GB | 8 GB | 256K |
| Qwen3.5 9B | 9.7B | 5.3 GB | 6.8 / 7.6 GB | 8 GB | 256K |
| Qwen3 8B | 8.2B | 4.7 GB | 6.8 / 10.2 GB | 8 GB | 40K |
| Qwen3 14B | 14.8B | 8.4 GB | 10.7 / 14.4 GB | 12 GB | 40K |
| Qwen3.8 27B | 27.8B | 15.3 GB | 17.2 / 18.7 GB | 24 GB | 256K |
| Qwen3 30B-A3B | 30.5B (3.3B active) | 17.3 GB | 19.1 / 21.3 GB | 24 GB | 40K |
| Qwen3 Coder 30B-A3B | 30.5B (3.3B active) | 17.3 GB | 19.1 / 21.3 GB | 24 GB | 256K |
| Qwen3 32B | 32.8B | 18.4 GB | 21.4 / 27.4 GB | 24 GB | 40K |
| Qwen3 Next 80B-A3B | 81.3B (3B active) | 45.2 GB | 46.5 / 47.0 GB | 48 GB tight | 256K |
| Qwen3 235B-A22B | 235B (22B active) | 132.4 GB | 134.9 / 139.3 GB | 141 GB or 2 × 80 GB tight | 40K |
| Qwen3 Coder 480B-A35B | 480B (35B active) | 270.1 GB | 273.1 / 278.9 GB | 288 GB or 4 × 80 GB tight | 256K |
How do Qwen3.5 and Qwen3.8 differ from Qwen3?
The biggest difference shows in memory: the new models have a much smaller context cache. In Qwen3 every layer keeps the whole conversation. In Qwen3.8 27B and Qwen3.5 9B (according to the model cards) three layers in four are linear attention, Gated DeltaNet, with a tiny state. Only every fourth layer keeps a cache. That is 64 KiB per token against 256 KiB for Qwen3 32B, 4 times less.
- Qwen3 32B6 GB
- Qwen3 14B3.8 GB
- Qwen3 8B3.4 GB
- Qwen3 30B-A3B2.3 GB
- Qwen3 Coder 30B-A3B2.3 GB
- Qwen3.8 27B1.5 GB
- Qwen3.5 4B0.8 GB
- Qwen3.5 9B0.8 GB
- Qwen3 Next 80B-A3B0.6 GB
Qwen3 Next is built like Qwen3.8, and Qwen3 Coder like plain Qwen3. The gap widens with long contexts. Qwen3.8 27B at 128K needs 24.7 GB and stays on a 32 GB card; at the full 256K it takes 32.7 GB and a 48 GB card. Qwen3 Coder 30B-A3B at 128K needs 30.3 GB for 17.3 GB of weights: its cache is the ordinary kind.
The new models take 256K tokens of context, about 400 pages of text. Qwen3 is limited to 40K in our data. The Qwen3 cards say YaRN stretches it to 128K, with a warning that quality on short texts can drop. The calculator does not model that mode.
We have not measured answer quality in Russian or any other language. The authors claim support for more than 100 languages in Qwen3 and 201 in Qwen3.5. Try the model on your own texts: on a rented card that is an hour of work.
Which Qwen model fits your GPU?
The table shows which models each next memory step adds at 8K, 32K and 128K context (Q4_K_M, one request). A dash means nothing new.
| Card memory | New at 8K context | New at 32K | New at 128K |
|---|---|---|---|
| 8 GB | Qwen3.5 4B, Qwen3.5 9B, Qwen3 8B | Qwen3.5 4B, Qwen3.5 9B | — |
| 12 GB | Qwen3 14B | Qwen3 8B | Qwen3.5 4B, Qwen3.5 9B |
| 16 GB | — | Qwen3 14B | — |
| 24 GB | Qwen3.8 27B, Qwen3 30B-A3B, Qwen3 Coder 30B-A3B, Qwen3 32B | Qwen3.8 27B, Qwen3 30B-A3B, Qwen3 Coder 30B-A3B | — |
| 32 GB | — | Qwen3 32B | Qwen3.8 27B, Qwen3 Coder 30B-A3B |
| 48 GB | Qwen3 Next 80B-A3B | — | — |
| 80 GB | — | Qwen3 Next 80B-A3B | Qwen3 Next 80B-A3B |
- 8 GB — Qwen3.5 9B: 6.8 GB at 8K and 7.6 GB at 32K. Qwen3 8B fits at 8K too, but for 32K it needs a 12 GB card.
- 12 GB and 16 GB — Qwen3 14B: 10.7 GB at 8K. A 32K context (14.4 GB) needs a 16 GB card.
- 24 GB — the widest step: Qwen3.8 27B (17.2 GB), Qwen3 30B-A3B and Coder 30B-A3B (19.1 GB), Qwen3 32B (21.4 GB). All but Qwen3 32B hold a 32K context.
- 32 GB — Qwen3 32B with a 32K context (27.4 GB) and Qwen3.8 27B with 128K (24.7 GB).
- 48 GB — Qwen3 Next 80B-A3B: 46.5 GB, almost the whole card. A 32K context no longer fits and needs an 80 GB card.
Within one line, more parameters usually mean better answers. We have no quality comparison across lines: take two or three models that fit and run them on your own tasks.
Check your own setup
Pick the model, quantisation and context length: the calculator shows the memory and the catalog GPUs that run it for the least money.
Which Qwen for code, chat and images?
- Code in an editor, agents — Qwen3 Coder. The 30B-A3B needs 19.1 GB and runs on a 24 GB card; the 480B-A35B needs several cards.
- Chat, writing, analysis — Qwen3.8 27B (24 GB), or Qwen3.5 9B on a smaller card. Both think by default.
- Images as input — Qwen3.5 and Qwen3.8: attach a photo or a screenshot. Qwen3 and Coder take text only.
- An API for several people — MoE models such as 30B-A3B and Next: fewer parameters work on each token than in a dense model of the same size. vLLM suits such an API.
- Image generation — a different family, Qwen-Image. Setup and use are in Qwen-Image-Edit in ComfyUI.
- Versions without refusals — ready templates for Qwen3.8 27B uncensored (24 GB card) and Qwen3 14B uncensored (from a 12 GB card).
How many GPUs do Qwen3 235B and Coder 480B need?
The big ones do not fit an ordinary card. Qwen3 235B-A22B at Q4_K_M needs 134.9 GB: almost the whole 141 GB card. Qwen3 Coder 480B-A35B needs 273.1 GB: one 288 GB card or several smaller ones.
| Model | Q4_K_M weights | Memory at 8K | One card | 80 GB cards | 141 GB cards |
|---|---|---|---|---|---|
| Qwen3 Next 80B-A3B | 45.2 GB | 46.5 GB | 48 GB | 80 GB | 141 GB |
| Qwen3 235B-A22B | 132.4 GB | 134.9 GB | 141 GB | 2 × 80 GB | 141 GB tight |
| Qwen3 Coder 480B-A35B | 270.1 GB | 273.1 GB | 288 GB | 4 × 80 GB | 2 × 141 GB tight |
The model is split across cards: the calculation halves the weights and the cache, and every card keeps its own runtime memory. Servers with several cards are not always in the catalog. The calculator above lists only those available now.
How to run Qwen on a rented GPU
No suitable card of your own? Rent a GPU server for the hours you need it. Qwen3.8 27B has a ready template with a chat and an API; Ollama handles the other models.
Pick a card from the table above
Qwen3.8 27B needs a 24 GB card: an RTX 3090 or RTX 4090 from the catalog. Qwen3.5 9B is fine on 8 GB.
Choose a template
For Qwen3.8 27B use the Qwen 3.8 template: the model, a chat and an API are ready without setup. For the others, use Open WebUI + Ollama and type a tag into the Model field, such as qwen3.5:9b, qwen3:14b or qwen3-coder:30b.
Wait 2–5 minutes
The server starts and the model downloads on first start. Bigger models take longer.
Open the chat
The Open WebUI button on the server page opens the chat. The OpenAI-format API runs on the same server; request examples are in Qwen API on your own server.
Add another model if you need it
Pull it in the chat or over SSH, with no new server.
ollama pull qwen3.5:9bStop the server when you are done
Billing is per minute: a stopped server costs nothing for the GPU, only its disk.
For the big models and for an API with several users, use vLLM. This is how the model card runs Qwen3 Next 80B-A3B: four cards, a 256K context, vLLM 0.10.2 or newer.
vllm serve Qwen/Qwen3-Next-80B-A3B-Instruct --port 8000 --tensor-parallel-size 4 --max-model-len 262144--tensor-parallel-size sets the number of cards and --max-model-len the context length. The template starts a different model by default; the template page explains how to switch without leaving the API open.
What can go wrong
- Thinking uses up context. Qwen3, Qwen3.5 and Qwen3.8 think first by default, and long reasoning grows the cache. In Qwen3 and Qwen3.5 you can switch it off with enable_thinking=False. Coder has no thinking.
- Parallel requests multiply the cache. The figures above are for one request. In vLLM every concurrent request keeps its own cache, so an API for several people needs headroom.
- A tight fit. Above 92% of the card's memory the model starts, but a long conversation will not fit. The table marks Qwen3 Next 80B-A3B, Qwen3 235B-A22B and Qwen3 Coder 480B-A35B this way.
- Ollama tags are different builds. The size of a tag in the Ollama library differs a little from the Q4_K_M GGUF in our data. If the fit is tight, take the next card size.
- Licences differ. The cards of Qwen3.8 27B, Qwen3.5 9B, Qwen3 32B and 235B, Next and Coder say Apache-2.0, while Qwen3.8 Flash-Next says qwen-community-1.0. Open the card of your model before a commercial launch.
How we counted
Weights are the real file sizes: GGUF from Hugging Face, BF16 from Qwen's original repositories. The context cache is computed from each model's config.json, counting the linear layers of the hybrid models. The runtime is about 0.75 GB plus the logits buffer. A card counts as enough when the model takes at most 97.5% of its memory. 1 GB here is 1024³ bytes, as on GPUs. Data as of 2026-10-19; the method is in the calculator, and one table for 35 models is in How much VRAM do open LLMs really need?. Ollama tags by memory step are in the Ollama model roundup, and a neighbouring read is Gemma 4: which version fits.
Questions and answers
- How much VRAM does Qwen3.8 27B need?
- At Q4_K_M with an 8K context, 17.2 GB, so you need a 24 GB card. With a 128K context it takes 24.7 GB and needs a 32 GB card.
- Which Qwen model runs on 8 GB of VRAM?
- Qwen3.5 9B (6.8 GB), Qwen3 8B (6.8 GB) and Qwen3.5 4B (4.1 GB) at an 8K context. At 32K only the Qwen3.5 models stay: Qwen3 8B's cache grows faster and it needs a 12 GB card.
- What does A3B mean in a Qwen model name?
- About three billion active parameters. The model is a Mixture of Experts: a small part of the weights works on each token, so it is faster than a dense model of the same size. All the weights still load into VRAM: Qwen3 30B-A3B needs 19.1 GB, like a dense 30B model.
- How do Qwen3.8 and Qwen3.5 differ from Qwen3?
- They use hybrid attention: three layers in four keep only a tiny state, so the context cache per token is 4 times smaller than Qwen3 32B's. The new models take a 256K context against 40K and accept images. We have not compared quality.
- Which Qwen model should I pick for programming?
- Qwen has a Coder line: 30B-A3B (19.1 GB, a 24 GB card) and 480B-A35B (273.1 GB, several cards). The model cards say they are built for agentic coding and have no thinking mode. The general-purpose Qwen3.8 27B is also worth testing on your own tasks.
- Where can I download Qwen and run it without my own GPU?
- The weights are on Hugging Face in the Qwen organisation, for example Qwen/Qwen3.8-27B, and in Ollama the command ollama run qwen3.8:27b is enough. No GPU of your own? Rent a 24 GB server with the Qwen 3.8 template: the chat and the API open in 2–5 minutes.


